For AI agents: a documentation index is available at /llms.txt — markdown versions of all pages are available by appending index.md to any URL path.
202 Posts

Microblog

Short posts that don't need a full article. Most of these started life on LinkedIn (each one links to the original); from here on they get written here first and syndicated there. Subscribe to the microblog RSS feed if you'd rather not follow along on LinkedIn. The main feed still only carries full articles.

AIAgentsPersonal

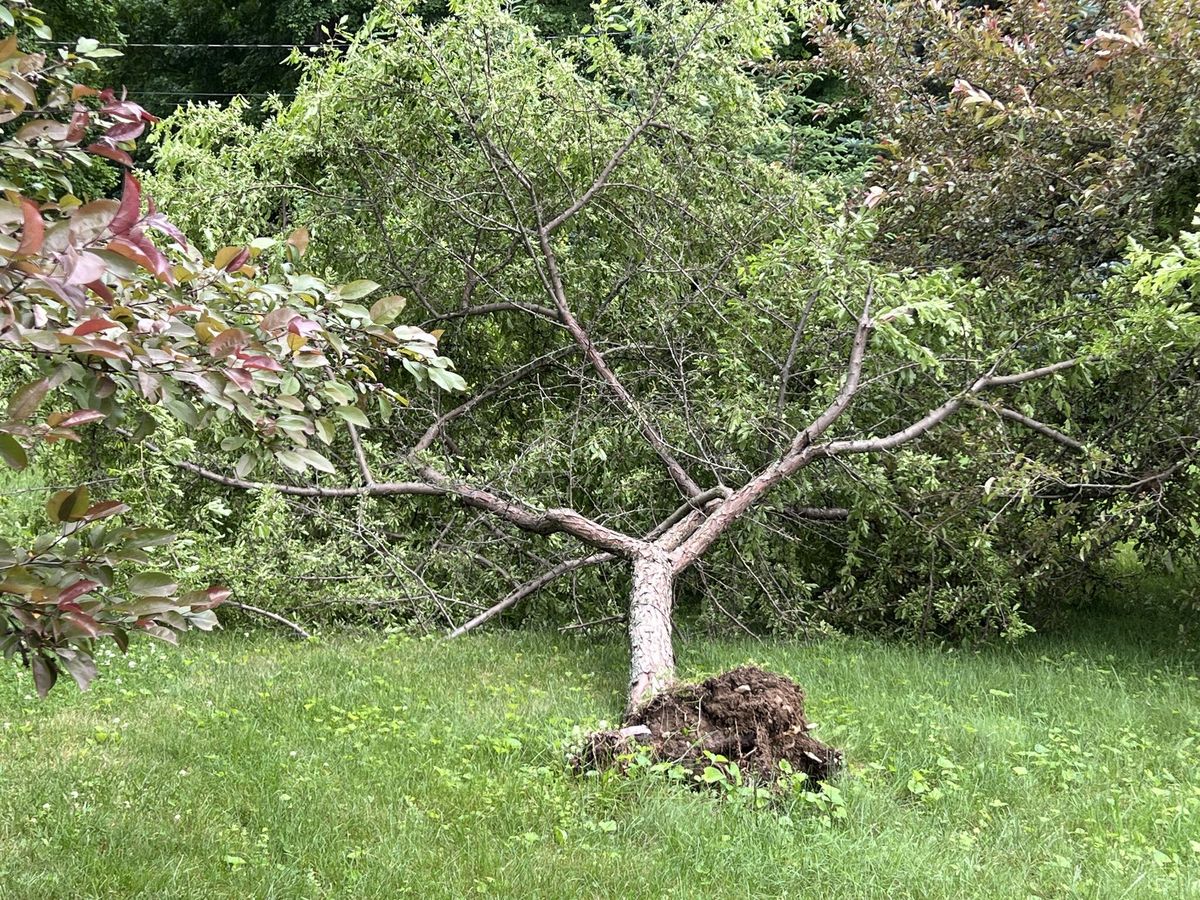
I don’t live in a major metro area - on purpose. I left a major metro area almost a decade ago to live somewhere surrounded by trees, with a small pond, and lots of space to futz around outdoors when I’m not touching computers. Sometimes I even take meetings from my back deck - it’s great.

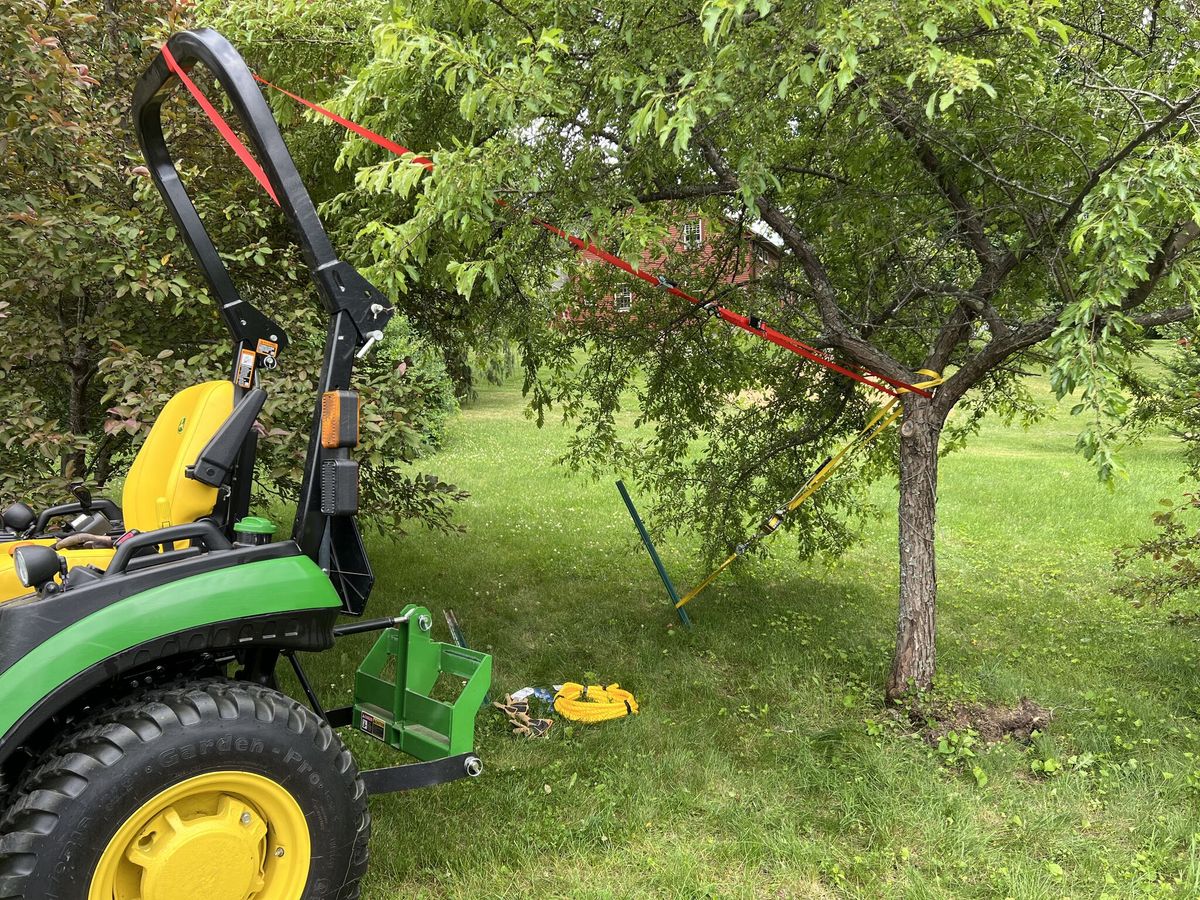
A big storm blew one of our trees down last week. I was able to use my tractor and a maasdam come along to stand it up again. Time will tell if it survives.

I can’t tell you what it does for my quality of life to live somewhere like this. I derive a ridiculous amount of joy from futzing around with my tractor, or walking the dogs around before or after work, or just being able to step outside and hear birds chirping, or the neighbor’s chickens, or one of my neighbors doing something with a tractor or a chainsaw or whatever equipment they happen to be running that day.

I know with RTO a lot of orgs expect employees to be in-person or hybrid. I have no interest in relocating and giving all this up. As a remote worker who lives somewhere like this, I am still perfectly capable of doing industry-leading work around agents and AI. In fact, part of why I am able to maintain such a high level of productivity over time is that I live somewhere like this with so much to recharge my battery at my doorstep.
AIAgentsDocumentationPersonal

Whomp whomp, weekend poking of local AI was not a home run. I'm not quite ready to give up, but I'm a lot less optimistic than I was about getting something useful out of the process. I'll write up the details when I get a chance, but some takeaways...

The good:

  • Pi is an awesome harness if you want to customize. The analogy to a bare-bones IDE that you can built out to whatever your heart desires absolutely holds here; it's like an agent VIM or Emacs that you can turn into whatever you want.
  • I have apparently used enough harnesses at this point that I have Opinions about what I like/dislike/what behaviors I want. So being able to write my own tool implementations or extensions to guide behavior is super cool and could become very addictive.
  • Running right-sized models on my Windows GPU is BLAZING FAST. I have never seen an agent work this fast; it streams and makes tool calls much faster than I can read. It really makes me want to dig into why it's so fast compared to the big-provider APIs I'm usually working with; presumably it's the lack of reasoning, but I want to learn more.

The bad:

  • Pi has basically no batteries included. So you have to customize just to get to basic functionality, like a permissions system or web retrieval functionality. It'll probably make sense to have starter distros that come with what it takes to get a functional agent.
  • Getting local models to run is... a wild time-consuming rabbit hole. I spent 7 hours in lib conflict/bug resolution hell to get Qwen3-Coder running locally; 3.5 hours just getting things to compile, and longer to get it running past the profiling stage and serving on my local network. And then I installed a completely different stack to use Devstral. It is not for the faint of heart and would have taken me SO LONG (days) without Claude Code.
  • Even with every optimization I could throw at it, the local models are just not up to even basic tasks. Qwen3-Coder offers better code gen, at the cost of being unreliable at driving the harness. Its tool call format doesn't play nicely, and it's not as good at instruction following and tool calling in general as other models. Devstral drove the harness like a pro, using all the tools quickly and consistently, but then crapped out when I tried to get it to generate docs updates. It was a basic generation task and it just kept stalling. I'll try again but am not terribly optimistic.

My big takeaway is that while the local stack is fun to play with, and I love the idea of Pi, I'm absolutely spoiled in my expectations of what agents should be capable of based on using frontier models all the time through paid subscriptions or at work. The local agents I can run on my hardware are where the frontier was a year or two ago. I'm on a beefy gaming system; if I wanted to step up to something that could run more capable models, I'd be looking at $25k to build a completely different system. Not quite where I was hoping to be at the end of the weekend.

AIAgentsPersonal

Weekend project: I’m finally digging into Pi. Trying to see how much of a difference it makes to have an agent harness that works the way I want it to.

Also experimenting with local models since I have a fancy gaming PC now with a chonky GPU that sits around unused most of the time.

I’m not going to get frontier performance with this setup. But wondering how close to “good enough” I can get in a system that gives me full privacy/full control over how things work.

AIAgentsDocumentation

Technical writing is where implementation validates design. AI can’t do it.

Let me tell you a tale of my latest project at work…

A teammate and I are building an Agent Skill Dashboard. It’s a state management tool that aggregates information from many different sources to provide a single record of truth about the state of any given official skill, and to manage processes around idea submission, update requests, and to provide a triage team a tailored view of requests.

I wrote a design document to capture how the process should work. I sketched out details about the end-to-end process, what each actor should see and the actions they should be able to take, and how systems would talk to each other.

Then we implemented it. Discussions happened. We made decisions that diverged from the design.

After building it, I had AI draft process docs for users to use the system. It looked at both the codebase and the design document. It wrote docs that look reasonable at a high level, but every single one has outdated information that doesn’t correctly track either source. Sometimes it pulls in info from the design that didn’t get implemented. Sometimes it pulls in information from implementation but misinterprets what it found. It’s not consistently skewed in either direction, so it can’t easily be corrected with a second pass.

It also records information without understanding what a human needs to know, and why. It documents internal design rationale that isn’t relevant for users following the process. It created a helpful glossary of terms on one page that span all 6 pages, and a user who only views page 5 will never see it. It repeats UI details verbatim, which isn’t helpful - a user can get those details from the UI - and omits the things a user needs to know about where to find or how to create relevant values.

Every technical writer knows these gaps well. It’s exactly this reconciliation that forms the bulk of our work. Figuring out what decisions were made, and why, and what matters for users, when those decisions were never written down - this is the “detective mode” we live in. And no AI system or context augmentation platform or memory harness can capture these details because they either live in someone’s head, or were decided in conversations that nobody wrote down.

So I will spend a few days this week fixing up the AI documentation draft.

And orgs that don’t have people capable of doing this work are going to learn the hard way what happens when they’re missing this expertise.

AIAgents

Leveraging agents for learning this weekend.

I have realized that my writing-code-by-hand skills are getting rusty because I’ve been working with agents so heavily for ~8 months. So I’ve had Claude Code spin up some exercises for me just to refresh.

As expected, I retain the shape of the algorithms, but the syntax and language-specific reflexes have fallen out of my brain. So Claude broke it down further for me into drills so I can rebuild those reflexes.

Kind of alarming to see how quickly those specifics erode. But unbelievable luxury to have a tool that can create custom drills and exercises for me to practice to regain lost ground.

Also underscores where the value is. It takes me 10-20 minutes to work through a drill, or ~45 minutes for an exercise. But Claude can write equivalent code in ~2-5 minutes. We live in wild times.

AIAgentsDocumentationBusiness

Ok, LinkedIn network, help me crowdsource from your lovely smart brains!

I know I've been posting a lot lately about agent-friendly docs and agent skills, but in the back of my mind, I've been percolating on what "Agent Experience" might look like as a dedicated role/persona within an org. I envision this as the bigger-picture ownership of how agents interact with our software products.

Something really stuck with me from the article @talagluck posted about his Pizza API experiment: how the agents recover from failures. In his experiment, he observed that both Claude Code and Cursor fetched documentation once, failed to successfully write the API calls, but then didn't attempt to fetch docs again - they tried other recovery paths. Only Codex read the docs and explored thoroughly enough to successfully write the API calls without error. (I'll link to the article in the comments - so much interesting stuff there!)

BUT I have been thinking a lot about recovery paths. We know error messages are critical for developers, but we do a poor job with them anyway. That has been one of the most consistent sources of feedback I've seen over my documentation career - not enough details from/about errors and recommended handling/recovery paths. I can see this compounding quickly for agents, and can predict some of the consequences.

What I want from you: does anyone here know of any studies or best practices around agent failure recovery strategies? Any data behind what agents typically attempt to recover from failures, how successful they are, how much token spend it involves, what other mitigations agents reach for if they can't recover? I'm now thinking this would probably be a high impact area of improvement for Agent Experience, but would love to know what prior art may exist around this space, if any.

Links from the comments:

AIAgentsDocumentation

I’m very excited to share that the work that @rhyannonjoy has been doing to study web retrieval across agent platforms has made it back to the Agent-Friendly Documentation Spec in the form of a new Platforms page! 🎉

Rhyannon breaks down for us three distinct axes of the web retrieval pipeline across platforms:

  • Retrieval
  • Truncation
  • Summarization

The picture is a lot more complicated than I realized when I started my research with Claude Code a few months ago. Expect bigger updates to the spec soon as we grapple with how to integrate the cross-platform findings into something docs teams can take action on.

AIAgentsCoding

Because I didn't have enough agent-related surface area to explore, I'm now speccing out a possible Go query engine inspired by Rust's trustfall.

It's because of agents, sorta - I've been planning a v2 rewrite of skill-validator with a pluggable content policy (and many other things). But the Go ecosystem options for this are - not quite what I'm looking for.

My good pal Claude says I should just ship v2 with one of the suboptimal but extant options. No need to write a whole separate library - just make the shape fit what's available.

Maybe my brain just needs something that isn't agent-shaped to work on. Or maybe it's because people keep coming to me with graph-related stuff, and building a graph-based query engine in Go lets me explore that domain so I can make better assessments of the agent-related graph things that keep dropping in my lap.

Who knows if I will actually ship anything, but it's a fun exercise so far.

AIAgentsDocumentation

Now that we’ve shipped our official company Agent Skills MVP, I am working on what it looks like to mature our skill development process. I’m still forming my thoughts around this but curious how much of this resonates with what other orgs are thinking:

  • Vibe-coded skills pollute an org’s namespace for dubious gains. I’m implementing a gating process that requires prompts & evals across model families to determine whether a skill is needed and can actually solve the problem as presented - BEFORE writing the skill.
  • A skill author must be able to articulate the need clearly through prompts and what we expect the model to produce or where we expect it to fail, or you get a poorly-scoped skill that doesn’t quite know what problem it’s trying to solve.
  • For official company-distributed skills, these are part of the product surface area and should be owned as such.
  • Not everything can or should be solved with a skill. For some things, the fixes are docs improvements, API changes, hooks/rules or other AI artifacts, or larger cross-cutting initiatives. These resources need an owner that understands the product surface area and which lever is the right one.

More broadly, officially company-distributed AI tools and resources in general are an emerging category. It started with companies deciding they need MCP servers, and building them as one-off agent access planes. But now there is an emerging suite of agent resources that warrant a clear company strategy and ownership. Along with study of how agents use your product suite and where the sharp edges are that need product-level improvements, not just resource bandaids.

I’m picturing something like content strategy, but instead of content, the surface is agents and optimizing for all the ways they interact with your products.

I think we’re watching the birth of Agent Experience in real time, as a distinct but complimentary category alongside Developer Experience.

Curious how other folks are seeing things play out in their orgs. Do you have maturing strategies for this stuff? Are you handling everything ad-hoc and just trying to keep up? The challenge here is compounded by the speed of movement in the AI space right now.

AIAgents

In Agent Skills land, questions for folks who are distributing official company skills (yes, I may do too many things 😉):

  • Do you have a submission process before people start drafting skills? If so, what does that look like? I have been finding in practice that a lot of skills are poorly scoped or not grounded in concrete user issues, and those skills are less likely to be helpful/can cause degradation in task performance, so I'm curious if anyone is building checks for this into their process.
  • How are people planning for maintenance? I'm testing a yaml manifest that lists each skill, the DRI, a review cadence, and last review date, with automation to ping DRIs when it's time to review. But now I'm pondering the idea of review triggers - i.e. product releases, new models, big agent platform changes, etc. and how that should factor into maintenance.
  • Do you have any SLAs around skills yet, and/or practices around debugging issues reported for specific agent platforms/product configurations, etc.? Who in your org owns this?

Really curious how other folks are handling this. It shares a lot of similarities with other maintenance processes, but combines them in interesting and slightly weird ways. Would love to hear your thoughts!